Learned this one the hard way. If you ask the equivalent of "what could I add to make this more useful?" you will get a lot of worthless suggestions like "I don't know, maybe make it sortable by the other column, too?" that don't move the needle at all on engagement.
Sometimes it's really hard or not worth to get proper feedback even when you have a userbase.
If I believe a feature is interesting or may be useful, I'll just spend least effort to create UI and make the feature barely useable for the simplest use case. Pretty much like a demo feature to hook up the users. It's actually pretty helpful to have bugs and limitations. If users find it could potentially solve their problems, or care about it, they will reach out and the ball can be rolling.
I have seen multiple projects that run into maintenance problems due to the large grammar with thousands lines and antlr 3/4 incompatibility.
Generally parser generator adds a layer of complexity/constraint which may be significant if you need full control of lexing, parsing, semantic processing, error recovery of your language.
After working on a few language projects (including core language, web-based editor with syntax coloring and auto-completion) myself I would strongly suggest hand-rolled parser for any serous language endeavour(general purpose or DSL).
I am a bit surprised by this, as I had the opposite experience. I find ANTLR grammars much more maintanable than the hand-written parsers I encountered. Indeed I was asked to port hand-written parsers to ANTLR for maintanability. Also, ANTLR4 seems to me to produce grammars which are clearer than ANTLR3.
The weak point is error recovering, in my opinion. While ANTLR offers a sort-of-decent error recovery strategy for free, one has to customize it if they want to get great error messages.
I think that many maintainability issues are due to poor usage of ANTLR. What we do is to:
1) Limit semantic actions
2) For complex languages do tree-transformations, after parsing
With this approach we got pretty decent results.
Personally I find hand-rolled parsers too costly to build and harder to maintain, but I have limited experience with them. I guess it also depends on the context: if you are designing a DSL while writing the parser you want to be able to evolve it very quickly and in that context I think that a parser generator is very useful. If instead I would need to build an industrial grade parser for a general purpose language, having a large budget, then I would go for an hand-rolled parser
My experience has been similar to yours. The company I work at has very complex business logic written as a custom DSL parsed/executed by a crazy pile of Perl code.
Recently we had requirements to come up with a way of providing on-the-fly validation in a web editor. This was only possible by ditching the old implementation and re-writing the grammar using ANTLR. While the old implementation is unmaintainable and (probably, who knows?) buggy, the ANTLR implementation is trivial to work on, test and add new features to.
If you're working with a limited time budget, which is common when your main job isn't to maintain the language, then parser generators such as ANTLR are a godsend. ANTLR even enables you to generate parsers in different languages depending on where it needs to be executed. Need something to run client-side, in the users browser? Generate a JavaScript parser and you're done. Need it to run in the Java backend? Generate it in Java and call it a day.
While it's true that error handling isn't the best, it's already better than nothing, and, as you say, can probably be improved with a bit of customization.
Second this. Recursive descent parsers are much easier in the long run, even if you can't immediately see your grammar after they have grown for a while.
From trying to understand parsing and RDPs I think I don't have the part of the brain required to understand it.
Not that it isn't simple, it is. But it seems examples (as usual) overexplain the simple things then overlook something that seems obvious but isn't.
The only time I managed to write a parser for simple math that wasn't an example was through the use of 'reverse production' parsing. Yes, it's the worse way, but it worked for me (this was a long time ago though)
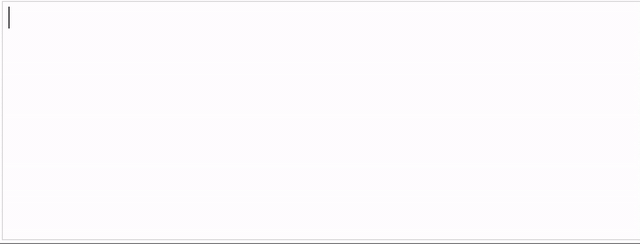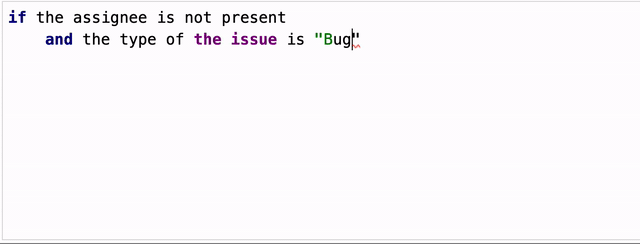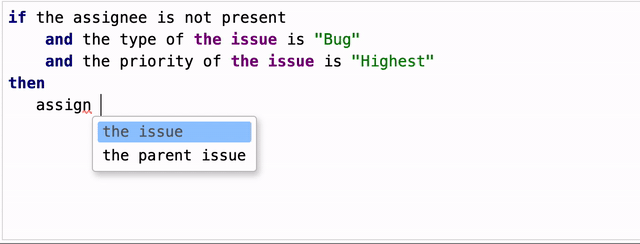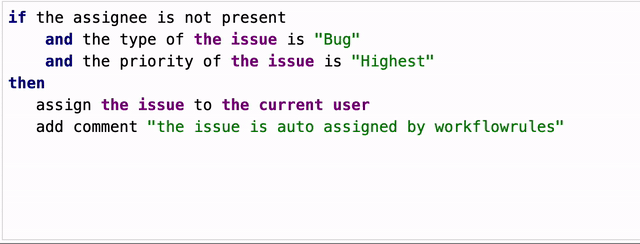
These are actually valid points for any DSL creation. I have been working on DSL for a few years. More precisely I'm working on a DSL tool that allows people to create "simple DSL that looks like english" so that normal people can use it. Here are my thoughts on those arguments.
Indeed complexity is there for most real domains. But DSL is meant to be another abstraction layer on top of the complexity. My lesson is constraint is the most important as this lays the foundation of its usefulness. I don't mean you should not have things like branch or loop. You certainly could add them, just in a domain friendly way that doesn't hurt the readability and writability of your DSL.
In order to tackle arbitrary complexity, the DSL itself should be designed with extensibility in mind so that technical people could easily add language constructs or vocabularies by using script or general purpose language. Further, those features should be able to be turned off for some scenarios. For those inherently complex stuff, they should be left to general purpose language anyway.
Tooling support is another big problem. In my opinion, DSL is never just the tiny language, it is about the language and tooling. However the tooling requirement is often not as standard as general purpose language. Domain users normally don't need an IDE(an editor should be generally required) or debugger. Rather, they want something that can be seamlessly integrated with the host application.
And more over, different people (even in the same domain) may have different requirements on DSL maintenance, eg, governance, versioning. This often leads to a case by case customization. I do not have a good answer for this other than the general advice: treat DSL and tooling as a whole and make the API as easy as possible for integration.
Edit: For anyone interested in my DSL(still work in progress), here is a glimpse: